Thursday, October 01, 2026

Recap Huawei Connect 2026

Initially posted on StorageNewsletter September 30, 2026

The 2026 edition of Huawei Connect, held recently in Shanghai, China, was once again an impressive conference, showcasing the breadth of the portfolio Huawei has rapidly designed, developed and brought to market across multiple technology domains. The main theme this year was "Advancing the Agentic World". More than 20,000 attendees from around the world joined the event, confirming the strength of the Huawei brand, its growing market penetration and the interest surrounding its technologies. Each edition also illustrates the speed of Huawei’s engineering teams and their ability to push the limits in performance, integration, scalability and resiliency.

Huawei used its annual flagship event to launch several products and introduce key innovations. We highlight five areas in particular: processors and accelerators, data interconnects, AI infrastructure, networking and cooling technologies.

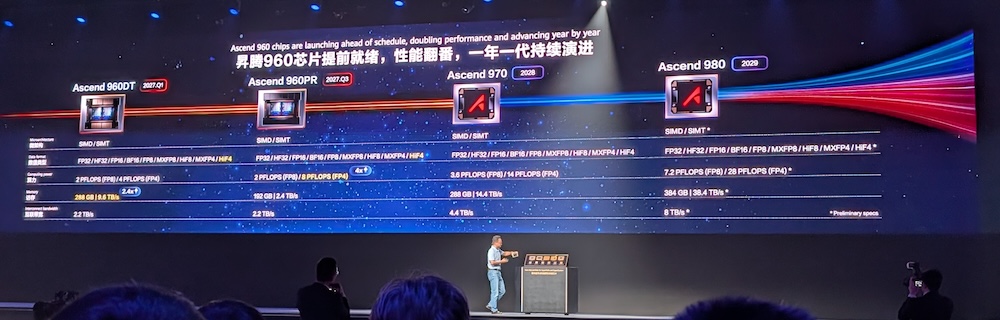
The first keynote, presented by David Wang, deputy chairman of the board and rotating chairman, immediately set the tone with updates to the Ascend roadmap, Huawei's AI accelerator family. The company has accelerated its schedule, with some products now expected significantly earlier than previously announced.

The Ascend 960DT is scheduled for Q1 2027, approximately two quarters earlier than initially planned, while the Ascend 960PR is expected in Q3 2027, also shortening the original delivery window. Specifications are ambitious, with at least 2 PFLOPS of FP8 performance and 4 PFLOPS at FP4, combined with up to 288GB of memory and 9.6TB/s of memory bandwidth.

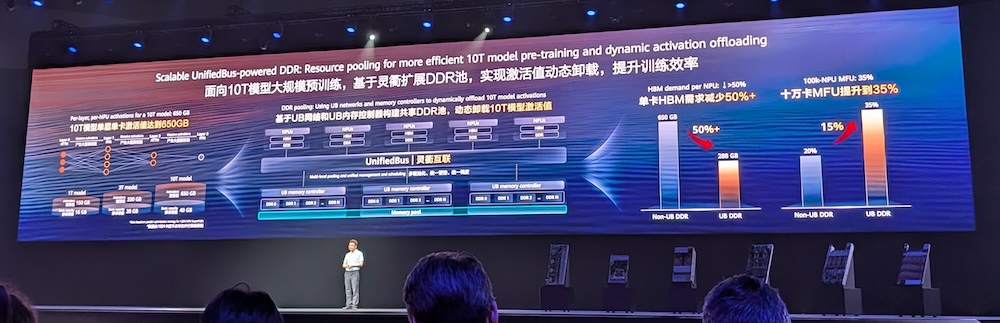
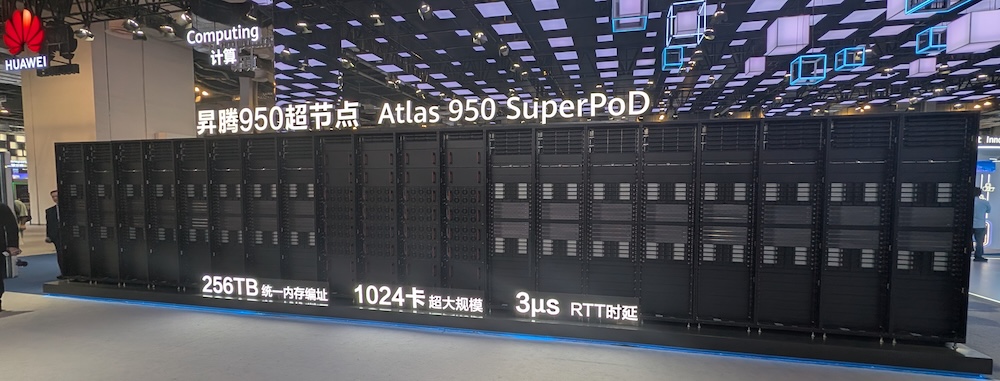
Nvidia continues to dominate this category, with its Rubin GPU offering 288GB of HBM4 and 19.2TB/s of memory bandwidth, exactly twice the figure announced for Ascend. Huawei’s strategy, however, is increasingly centered on pooling large numbers of compute resources to deliver aggregate performance at massive scale. This is the promise behind its SuperCluster and SuperPod architectures, combining Kunpeng CPUs, TaiShan systems and Ascend accelerators through the latest generation of UnifiedBus (UB).

Huawei’s networking team has also made significant progress with Hi-ONE, its new interconnect technology based on a Near-Packaged Optics (NPO) approach. The architecture can combine approximately 5,500 Hi-ONE modules to build very large clusters while reducing the number of network hops and lowering latency.

Closely related to this strategy is UnifiedBus, which Huawei presents as an advanced peer-to-peer interconnect architecture capable of linking different types of components, including CPUs, NPUs, DPUs, memory, storage devices, NICs and switches. The technology remains largely confined to the Huawei ecosystem today, but its architectural scope is broader in terms of device types than many alternatives currently available in the industry.

Facing UB are technologies such as Nvidia NVLink, UALink and even CXL, each addressing different parts of the interconnect challenge with its own strengths and limitations. There is clearly an intense technology race underway in this domain as AI infrastructure increasingly depends on the ability to efficiently connect compute, memory, networking and storage resources.

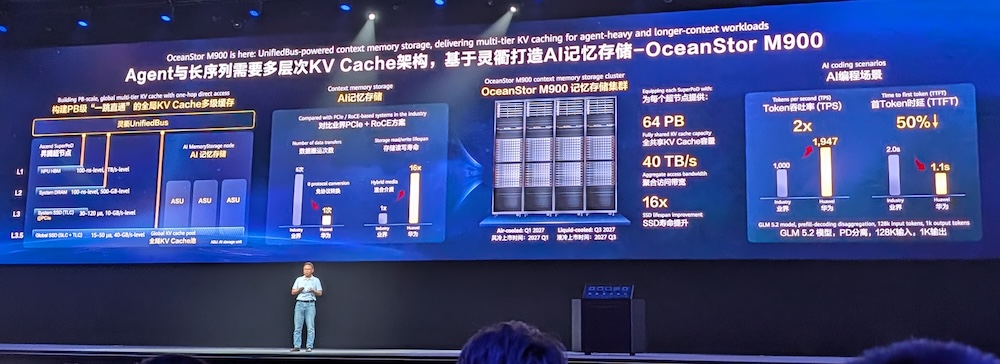
On the storage side, Huawei clearly emphasized AI infrastructure. While its traditional storage families continue to evolve, the most interesting development is Context Memory Storage, designed around KV cache workloads. Huawei currently offers the M800 and plans to introduce the M900 in early 2027.

The M900 will be available in two configurations: a 2U air-cooled appliance and a 1U liquid-cooled model. A cluster can scale to 64PB, while each appliance integrates 12 ASUs, or AI Storage Units, each providing 64TB.

According to Huawei, the architecture eliminates protocol conversion and CPU forwarding, reducing access latency from milliseconds to approximately 60 microseconds. A single cluster can deliver up to 40TB/s of aggregate access bandwidth, which Huawei says is 1.5× higher than competing solutions.

The current M800 is based on the OceanDisk 1800 architecture, a family that Huawei is now extending with the OceanDisk 1610. The company is also partnering with ThinkParQ around BeeGFS to address HPC and AI workloads. This initiative illustrates Huawei’s desire to expand its software partner ecosystem in high-performance storage, and we expect additional partnerships in this area.

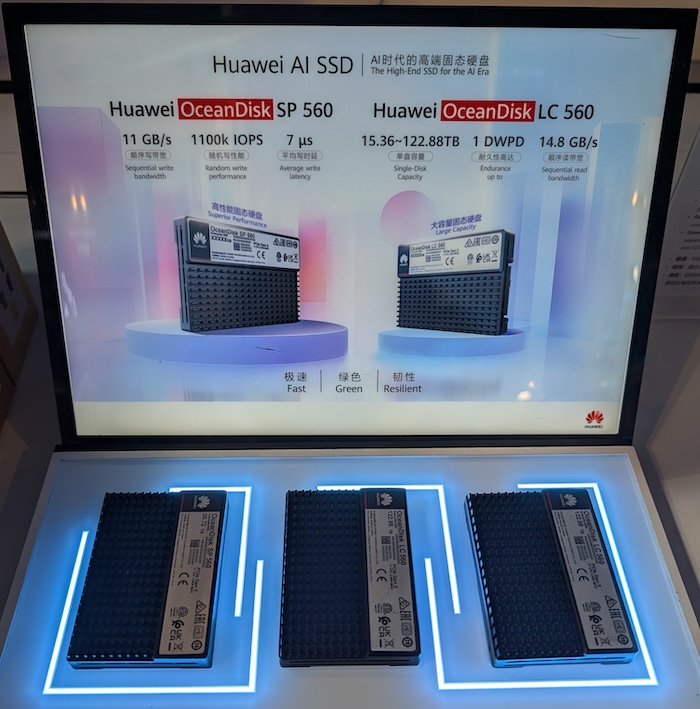
Regarding its SSD strategy, Huawei confirmed multiple models covering different capacities and interfaces, with capacities currently reaching 122TB. Its magnetic disk initiative has been somewhat delayed but is still expected to materialize over the next few quarters.

On the cloud side, Huawei Cloud officially launched its latest AI Cluster Service (AICS) globally, positioning it as an infrastructure foundation for agentic AI and a way for enterprises to extend their internal environments with flexible external resources. Huawei also highlighted its Agentic Model-as-a-Service (MaaS) platform, designed to accelerate enterprise adoption of AI agents and models.

One impression remains constant from one Huawei Connect to another: the remarkable pace at which Huawei’s engineering teams introduce new technologies and products across an increasingly broad range of infrastructure layers.

The conference was also an opportunity to meet partners and end users from many regions, all interested in learning more about Huawei's technology roadmap. Another interesting keynote came from Jim Zemlin, executive director of the Linux Foundation, who naturally emphasized the strategic importance of open source and illustrated its momentum with several concrete examples.

This software and open-source dimension is particularly important for Huawei. Expanding the ecosystem around its processors, clusters, UnifiedBus architecture and other infrastructure technologies will be critical to broader adoption. Hardware performance alone is not sufficient; software compatibility, developer support and a strong partner ecosystem will play an equally important role.

Huawei Connect 2026 ultimately demonstrated once again the extraordinary breadth of Huawei's IT portfolio. From processors and AI accelerators to networking, interconnects, storage, cloud infrastructure and cooling, the company continues to expand across virtually every layer of the modern data center stack.

Share:

Tuesday, September 29, 2026

70th Edition of The IT Press Tour back in Silicon Valley

The IT Press Tour, a media event launched in June 2010, announced participating companies for the 70th edition organized in Silicon Valley the week of October 5th, 2026.

During this edition, the press group will meet 8 hot and innovative companies:
  • Clockwork, an IT infrastructure optimization software company,
  • Cohesity, a leader in modern data protection,
  • CTera, a reference in distributed file storage,
  • DDN, a top player in high performance storage dedicated to HPC and AI,
  • Hammerspace, a software player in parallel file storage,
  • Phison, a fast growing SSD vendor,
  • ScaleFlux, an innovator in SSD controller and CXL
  • and VergeIO, an alternative to VMware.

I invite you to follow us on Twitter with #ITPT and @ITPressTour, my twitter handle and @CDP_FST and journalists' respective handle.
Share:

Thursday, September 10, 2026

DataCore made a significant step towards product unification and automation

Another session during the 69th edition of The IT Press Tour, held last week in Ljubljana, Slovenia, featured DataCore, a well-established and recognized player in the Software-Defined Storage market.

Said Boukhizou, recently promoted VP of Products at DataCore, reintroduced the company and highlighted two strategic directions, both fueled by an active acquisition strategy: the unification of the product portfolio and the addition of AI-driven services. The presentation followed a four-act narrative: why infrastructure freedom still matters, how acquisitions have expanded DataCore’s capabilities, the transition from integration to a unified platform, and finally the introduction of agentic AI into storage operations.

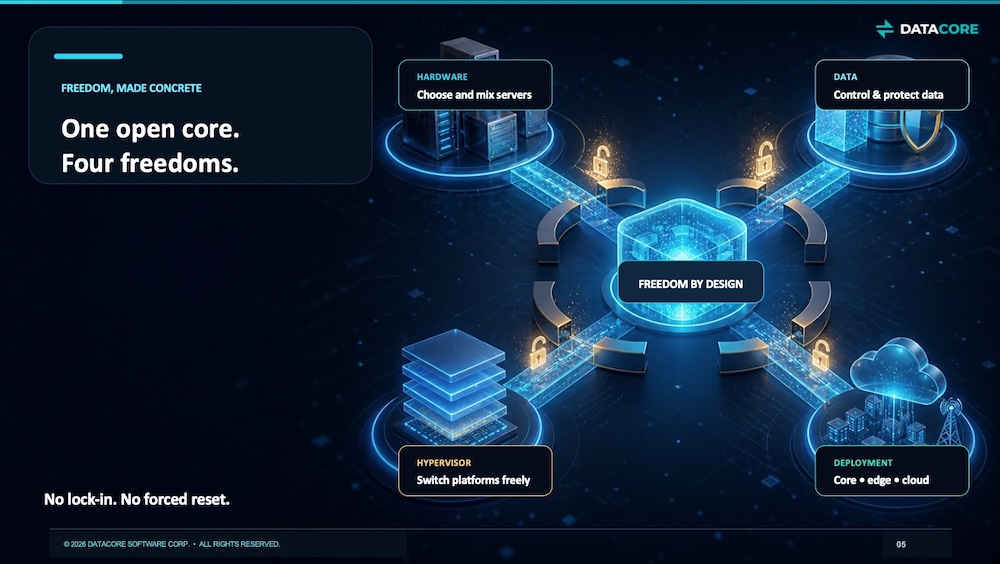
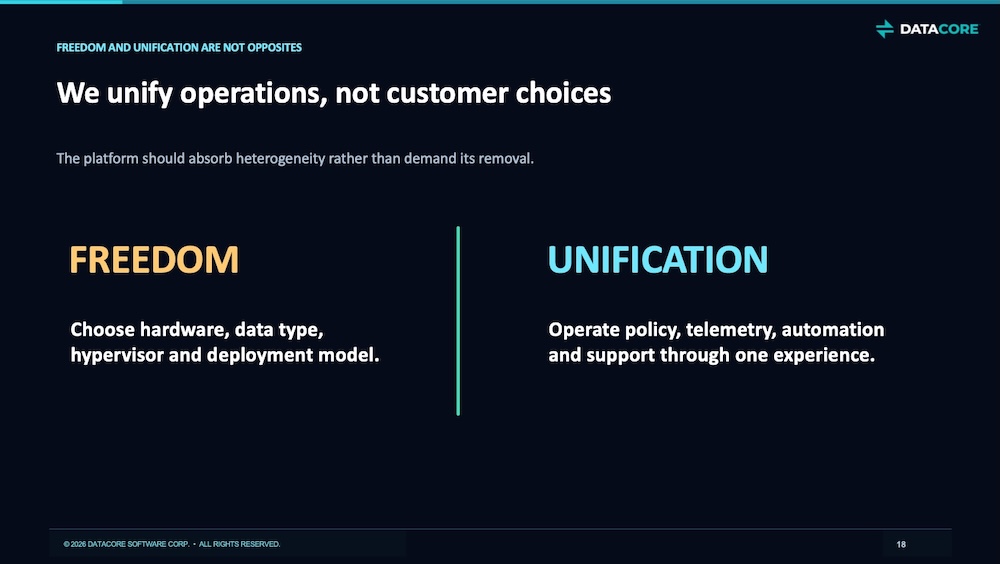
DataCore’s original mission remains unchanged: give customers and partners freedom from infrastructure constraints, platform barriers and data lock-in, allowing them to build and evolve their technology stacks on their own terms. The company translates this philosophy into “four freedoms,” all built around one open core: hardware, with the ability to choose and mix servers; data, maintaining control and protection; hypervisor, with the flexibility to change virtualization platforms; and deployment, spanning core, edge and cloud environments.

This approach has particular relevance in a market where server availability and infrastructure costs remain under pressure. DataCore allows organizations to choose, mix, reuse and refurbish standard x86 hardware from different vendors, reducing hardware dependency. The uncertainty created by Broadcom’s acquisition of VMware also reinforces this positioning. Customers can move between hypervisors such as ESXi, Hyper-V, Proxmox, XCP-ng and Xen while maintaining independent data services and operational continuity.

At the same time, enterprise data is no longer centralized. It is increasingly distributed across core infrastructure, edge locations, cloud-native environments and AI workloads, each requiring different levels of performance, economics and resilience. DataCore refers to this reality as “plurality,” where freedom becomes more valuable but also more complex to manage.

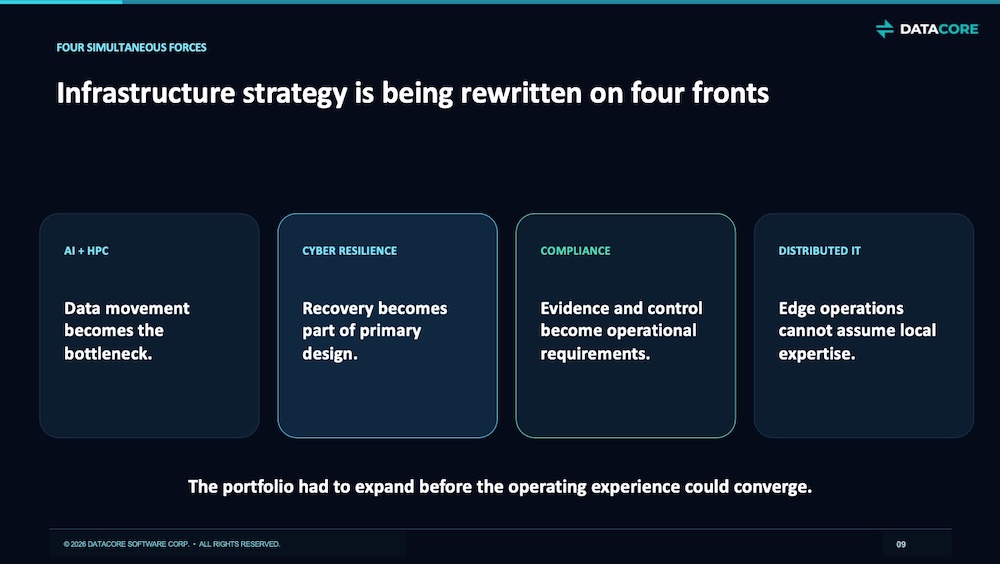
Four major forces are simultaneously reshaping infrastructure strategies. AI and HPC are exposing data-movement bottlenecks; cyber resilience is making recovery a fundamental architectural requirement; regulations such as NIS2, DORA and the Cyber Resilience Act increasingly require evidence of recoverability, tested recovery points and audit trails rather than simply architecture diagrams; and distributed IT continues to expand into edge environments where local technical expertise is often limited.

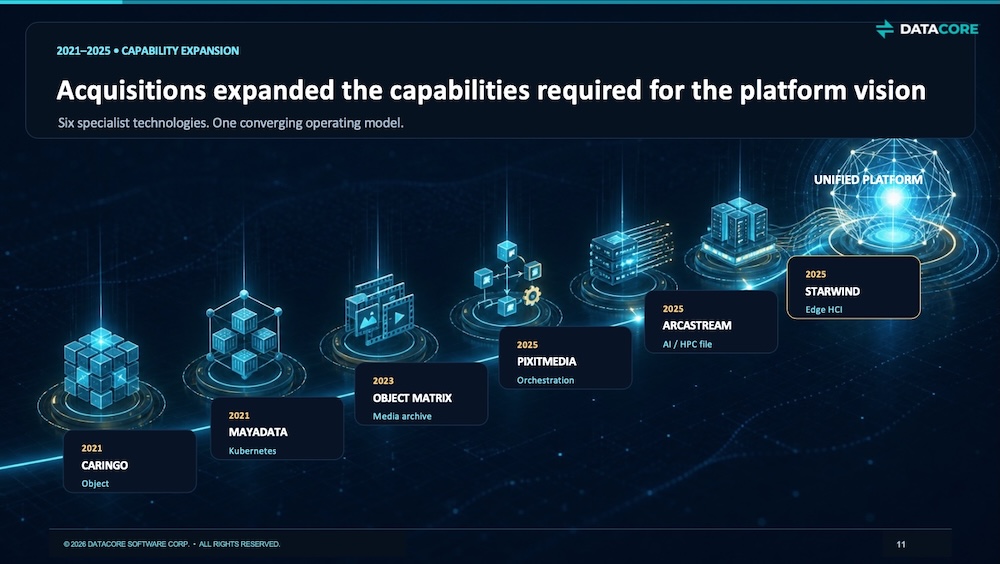
DataCore has significantly broadened its capabilities through acquisitions. The company highlighted six during the presentation: Caringo for object storage in 2021, MayaData for Kubernetes storage in 2021, Object Matrix for media archive in 2023, Pixitmedia for orchestration in 2025, Arcastream for AI/HPC file environments in 2025, and StarWind for edge HCI in 2025.

The key message, however, is that “breadth ≠ unity.” Acquiring specialized technologies represents only the first phase. The real challenge is to unify engineering direction, go-to-market execution, APIs, identity, telemetry and operational functions such as support and lifecycle management.

A few questions remain around this acquisition narrative. We don't know why WIN, acquired in 2023, was not included in the list, and we remain surprised by the way Pixitmedia and Arcastream are sometimes presented. More importantly, DataCore continues to position Arcastream as a parallel file system alongside products such as Swarm and SANsymphony, which provide native object and block storage respectively. Arcastream relies on IBM GPFS, later Spectrum Scale and now Storage Scale, as its underlying parallel file system, adding management and orchestration capabilities on top.

The file storage question is not new for DataCore. As we wrote several years ago, the company clearly needed a file storage offering to complement its portfolio. This explains the 2019 OEM agreement with Hammerspace, when its technology was offered by DataCore under the vFilO name for a limited period.

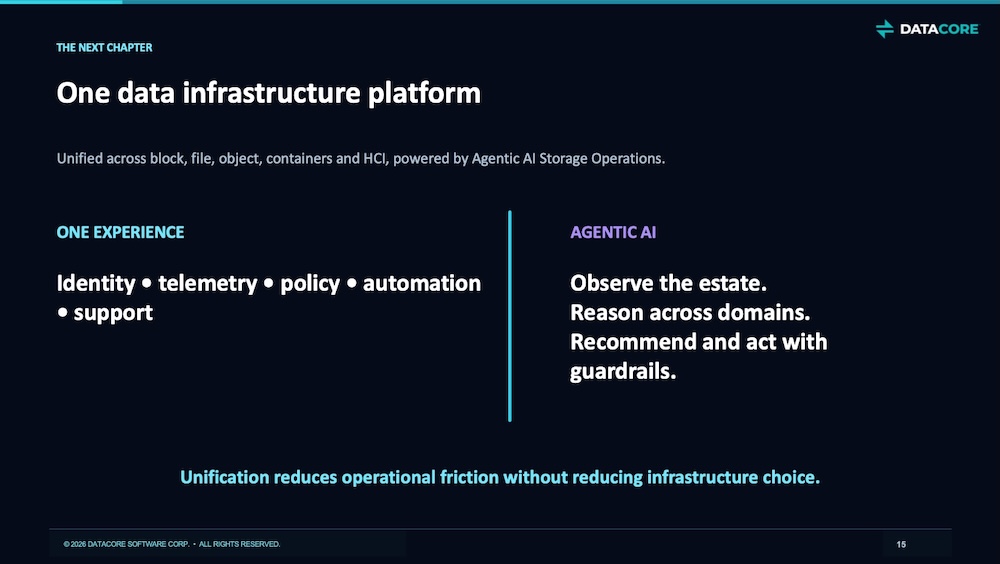
The broader strategy has now clearly evolved from acquisition to integration and ultimately toward a single platform. DataCore summarizes this transformation as Acquire → Integrate → Unify → Autonomize. The ambition is to converge block, file, object, container and HCI storage under one platform experience, sharing identity, telemetry, policy, automation and support while preserving infrastructure choice underneath.

Portfolio unification therefore represents a fundamental component of DataCore’s strategy, but the next step goes further with the introduction of agentic AI into IT and storage operations.

DataCore wants to move beyond dashboards that simply describe problems toward systems capable of helping administrators resolve them. The proposed operational loop follows an Observe → Reason → Recommend → Act model, with human-defined policies and approvals remaining the ultimate control plane. Guardrails include policies, approvals, auditability, rollback mechanisms and explainability.

Initial use cases include capacity prediction, performance bottleneck detection, cyber-resilience verification, compliance monitoring, lifecycle management and support diagnostics. The objective is progressively to automate routine operational decisions while maintaining human oversight for critical actions.

As Said Boukhizou clearly explained during the session, DataCore now has several technology engines moving toward the same destination: SANsymphony for block storage; StarWind for edge, ROBO and SMB HCI; Swarm for cyber-resilient S3 and archive storage; Nexus for parallel file and orchestration; and Puls8 for Kubernetes storage.

The strategic direction is now much clearer: DataCore has spent several years assembling the pieces through acquisitions and is entering the more difficult phase of turning them into a coherent platform. The transition from a collection of specialized storage technologies to a unified operating experience, eventually enhanced by agentic AI, will therefore be one of the key elements to watch.

We expect additional product details around IBC 2026 and later during DataCore Days. These announcements should provide a better indication of how far the company has progressed on product unification, AI-driven operations and its broader corporate trajectory, topics that remain particularly important for DataCore, its executives, employees, investors and industry observers.

Share:

Friday, August 28, 2026

Recap FMS 2026

Initially posted on StorageNewsletter August 25, 2026

A few months ago, Terrapinn acquired FMS, raising plenty of expectations for this year's edition, and we were not disappointed. In just a few months, the event team managed to introduce several meaningful improvements and changes. The logo and overall visual identity were completely redesigned, giving FMS a welcome refresh, while the organizers wisely preserved what already worked well: the expo floor, of course, but above all the conference program, a particularly rich component that gives the event its unique flavor.

Organizers shared the latest attendance figures, with more than 4,000 participants across all profiles, exceeding the numbers recorded during recent editions. This is clearly a positive sign. The exhibitor list was also solid with classic or let's say "usual suspects" even if some vendors preferred not to exhibit and instead secured private meeting rooms nearby. We noticed several absences from the show floor, although some of these companies still appeared on the conference agenda despite having no physical booth. Nvidia, for instance, was invited twice on the main stage without exhibiting. Other notable absences included Phison, Swissbit and Panmnesia, while newcomers such as Primemas appeared alongside returning names including ScaleFlux, Winbond and YMTC. We still wonder, however, why some vendors participate in the event when their businesses are relatively far removed from the component, memory or device level.

In terms of topics, there is no doubt that AI now drives almost everything in IT and, obviously, memory and storage are no exception. The now-famous "Memory Wall" was on everyone's lips and featured prominently across virtually all keynotes. It is a very real challenge, pushing vendors to innovate and explore different approaches. It has triggered initiatives around KV cache, HBF through the Sandisk and SK hynix collaboration, new iterations of CXL that received significant attention, as well as more traditional subjects such as high-capacity SSDs, TLC and QLC NAND, and PCIe Gen 5 and Gen 6.

The Memory Wall also prompted several speakers, both during keynotes and breakout sessions, to revisit the concept of a new memory and storage hierarchy. As AI increasingly moves into the inference phase, the ability to preserve context, reduce token usage, improve QoS and ultimately lower TCO becomes essential.

As we all know, AI training is primarily about compute, while AI inference is increasingly about memory. More concretely, we can group the five major themes of the conference as follows:

  1. AI inference and the emerging memory/storage hierarchy
  2. New NAND technologies, including BiCS10, V-NAND, XL-Flash and HBF
  3. Connectivity, particularly PCIe Gen 5 and Gen 6
  4. Memory pooling and sharing with CXL 3.2
  5. Energy consumption and cooling


Among the dense vendor presence, we selected several announcements that readers can explore in full on our dedicated FMS page:
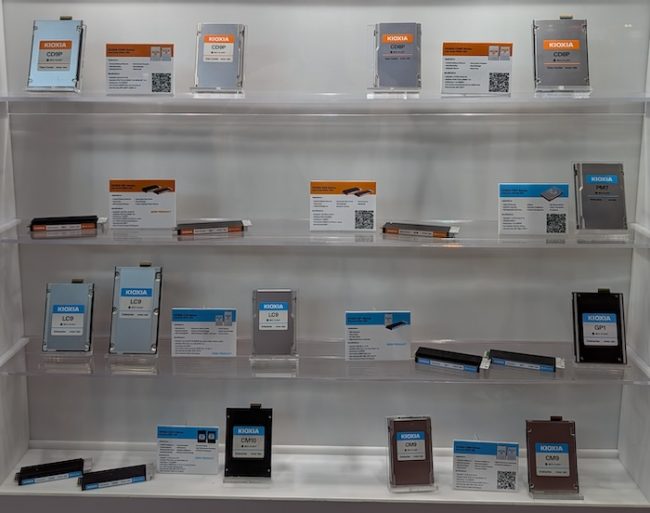
  • Kioxia unveiled the CM10 Series, presented as the first PCIe Gen 6 enterprise SSD built on 332-layer BiCS FLASH Generation 10 TLC memory. The company also showcased its GP1 Series ultra-high-IOPS SSDs, XL1 Series with second-generation XL-FLASH, and next-generation E1.S SSDs
  • Samsung unveiled its next-generation 3D Memory vision, outlining the future of AI infrastructure. It also displayed several new SSDs, including the 256TB BM1773 in E3.S and U.2 form factors, alongside the PM1763, its V-NAND V10 approach, HBM4 and CXL memory modules
  • Micron also had a significant presence, with demonstrations involving partners including Astera Labs and Microchip
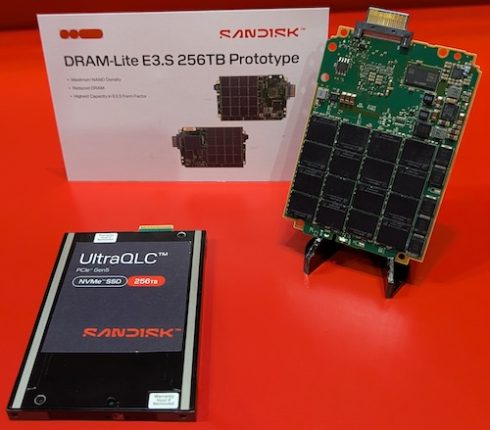
  • Sandisk showcased HBF alongside BiCS10 NAND and an UltraQLC E3.S 256TB prototype
  • Sandisk and SK hynix also released the first OCP Technical Specification for High Bandwidth Flash standardization
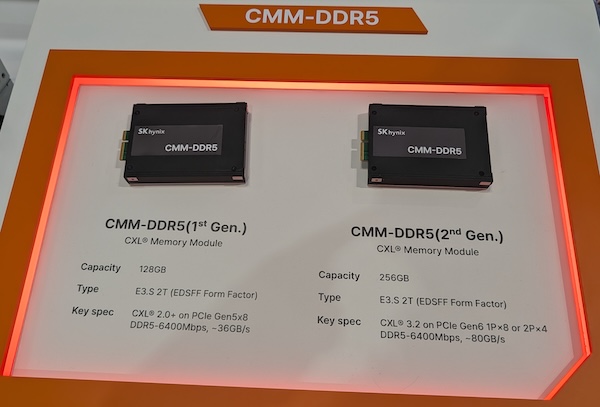
  • SK hynix showcased several new and recently introduced products across HBM, NAND, SSDs and CXL memory
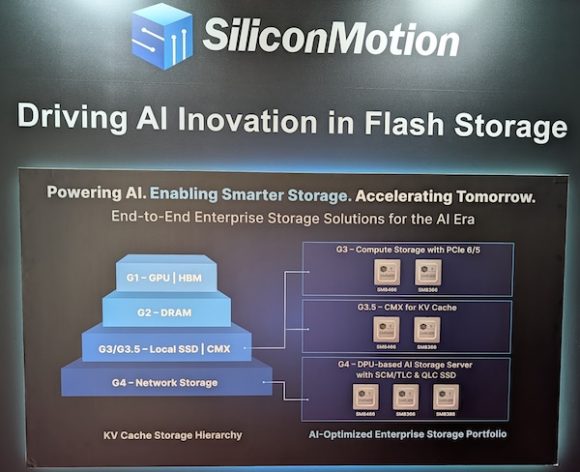
  • Silicon Motion unveiled its MonTitan SSD Reference Design Kit for AI infrastructure and showcased next-generation storage solutions for agentic AI, alongside a joint automotive platform demonstration with MediaTek
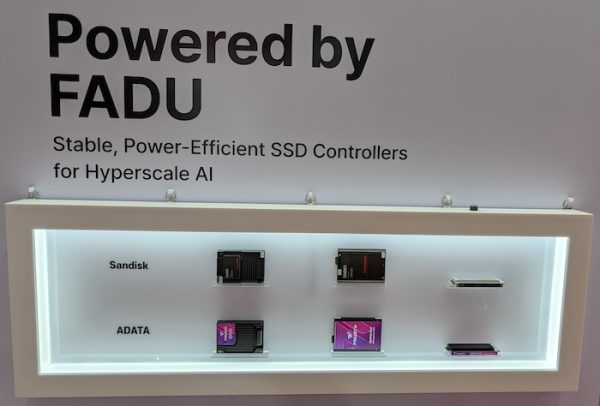
  • FADU maintained a strong booth presence and demonstrated SSD controllers with several partners
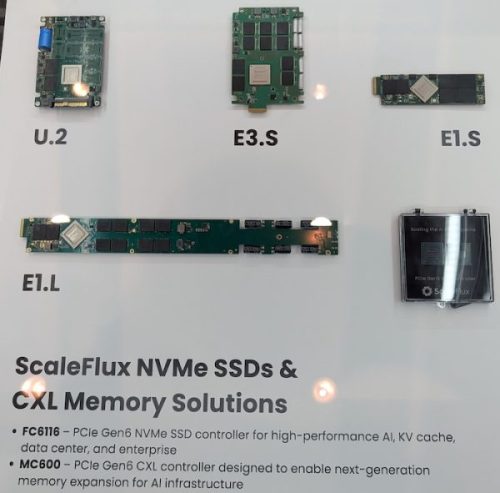
  • ScaleFlux showcased PCIe Gen 6 SSDs and CXL memory controllers
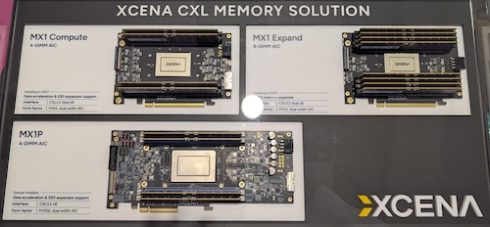
  • Xcena displayed its MX1 product line
  • TenaFe demonstrated PCIe Gen 5 SSD solutions targeting AI, Edge AI and DRAMless data center boot applications
  • Intel hosted four companies on its booth, Montage, Micron, Xcena and Marvell, to demonstrate memory expansion technologies
  • Innodisk introduced DDR5 12,800 MT/s MRDIMM modules
  • Longsys discussed its Edge AI storage fusion strategy
  • DapuStor presented its 512TB SSD
  • NEO Semiconductor launched the NEO.AI Memory Platform
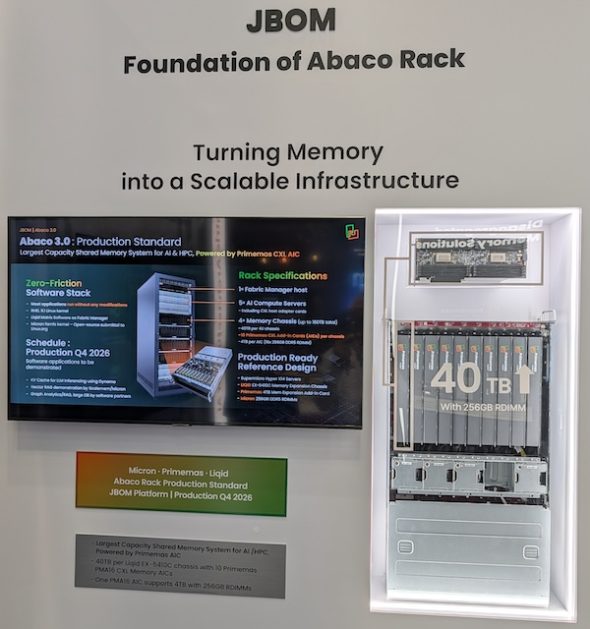
  • Liqid, together with Micron and Primemas, displayed the Abaco 3.0 Rack on the Primemas booth
  • Teledyne LeCroy announced that its Summit M616 protocol analyzer is now PCIe 7.0-ready
  • OmniCore quietly launched its all-SSD NAS
  • Xsight Labs announced a new funding round of more than $300 million at a $2.8 billion valuation

Beyond hyperscalers, neoclouds, universities and research centers, we hope the event will attract a broader range of enterprise end users in the future, creating a more balanced attendee profile. This is one area where we would like to see further progress in upcoming editions.

We invite all our readers to visit our dedicated FMS page, where they can find this recap together with all the news and announcements made by sponsors, exhibitors, industry associations and partners during the event.

The 2027 edition of FMS will return to the same location, but earlier in the year, from July 27 to 29, 2027. And there is something new: the team has launched the European edition of FMS, scheduled for October 19–20, 2027 at RAI Amsterdam in the Netherlands.

Share:

Tuesday, August 25, 2026

69th Edition of The IT Press Tour in Ljubljana, Slovenia

The IT Press Tour, a media event launched in June 2010, announced participating companies for the 69th edition organized in Ljubljana, Slovenia, September 1st and 2nd, 2026.

During this edition, the press group will meet 6 hot and innovative companies:
  • Cybee, a young French backup software company,
  • DataCore, the established storage virtualization vendor,
  • ExpectedIT, an young infrastructure software company,
  • HYCU, a leader in SaaS data protection,
  • StratoFoundry, a young french AI oriented data management company,
  • and Veridion, an data service company being the Google for corporate information.

I invite you to follow us on Twitter with #ITPT and @ITPressTour, my twitter handle and @CDP_FST and journalists' respective handle.
Share:

Tuesday, June 23, 2026

JuiceFS, a fast growing file storage for massive volume of data

At the 68th IT Press Tour, Joe Zhou, Developer Relations Engineer at JuiceFS developer Juicedata, presented an update on the company's vision for cloud-native storage and the rapidly evolving role of object storage in modern data infrastructure. Rather than focusing solely on JuiceFS itself, Zhou framed the discussion around a broader industry transition in which object storage has become the foundational storage layer for AI, analytics, databases, and cloud-native applications. His central argument was that while object storage has become the dominant persistence layer because of its economics and scalability, it remains too primitive for most enterprise workloads. As a result, an entire generation of software—including distributed databases, vector stores, streaming platforms, and file systems—is emerging to provide richer interfaces while continuing to use immutable object storage as the underlying medium.

According to Zhou, object storage has evolved from being a simple archival technology into the de facto backend of modern cloud infrastructure. He pointed to a growing list of platforms that are now fundamentally built on object storage rather than block or file storage. Examples include AI databases such as LanceDB, Chroma, and Milvus; cloud databases including Neon, which was recently acquired by Databricks; distributed SQL platforms such as TiDB; streaming systems like WarpStream; analytics engines; and newer cloud-native storage systems such as turbopuffer, used by companies including Anthropic and Notion. JuiceFS itself belongs to this category of technologies that leverage object storage while presenting applications with more familiar interfaces. The breadth of these examples illustrated that object storage is no longer confined to backup or archival use cases but has become the persistence layer underpinning modern data platforms.


The appeal of object storage, Zhou explained, is based on several structural advantages that are difficult for traditional storage architectures to match. Object stores expose an extremely simple API built around operations such as PUT, GET, and Compare-and-Swap. This simplicity enables hyperscale cloud providers to deliver extraordinary scalability while maintaining operational efficiency. Unlike conventional file systems, object stores employ a flat namespace rather than hierarchical directories, allowing virtually unlimited scaling without the metadata bottlenecks associated with traditional storage architectures. Public cloud object storage services also routinely advertise eleven nines (99.999999999%) of data durability and support multi-region availability for high resilience. Combined with features such as immutability and exceptionally low storage costs—typically around two cents per gigabyte per month in major cloud regions—object storage has become the most economical and reliable long-term storage platform available.

Despite these strengths, Zhou argued that object storage is fundamentally unsuitable for many application workloads when used directly. Most enterprise software expects richer file system semantics than object stores provide. Objects cannot be modified in place, meaning even minor updates often require entire files to be rewritten. Directory hierarchies do not actually exist, instead being simulated through indexed prefixes that become increasingly expensive to manage as environments scale. Batch metadata operations such as renaming large directory trees are slow and costly because they involve manipulating enormous numbers of object keys. Object stores also exhibit higher latency than conventional file systems, cannot execute applications directly, and perform poorly when managing structured datasets composed of many related files. These limitations create friction for AI pipelines, software development environments, analytics platforms, and enterprise applications originally designed around POSIX file systems.

According to Zhou, these shortcomings explain why many modern cloud-native systems are effectively rebuilding traditional interfaces on top of object storage. Instead of abandoning POSIX or relational database interfaces, companies increasingly expose familiar APIs while using object storage solely as the persistence layer. JuiceFS provides POSIX compatibility, Neon delivers PostgreSQL semantics over object storage, and numerous modern databases perform similar abstraction for their respective workloads. The trend reflects an industry consensus that object storage offers compelling economics but requires additional software layers before it becomes practical for mainstream computing.

A significant portion of the presentation examined Amazon Web Services' recently introduced S3 Files service, released in April 2026. Zhou described the product as "a decent approach" that validates JuiceFS's overall architectural direction but argued that AWS's implementation remains constrained by important design decisions. S3 Files enables customers to mount an S3 bucket as a POSIX-compatible NFS file system by placing Amazon Elastic File System (EFS) in front of S3. Within this architecture, EFS acts as both the metadata layer and high-performance cache while S3 remains the authoritative copy of all data.

The system employs a strict one-to-one relationship between files and objects. Small files, particularly those below the default threshold of 128 kilobytes, remain optimized for low-latency access through the EFS layer. Write operations are initially committed to EFS before being synchronized back to S3 after approximately sixty seconds. Although this approach improves responsiveness compared with accessing S3 directly, Zhou argued that it introduces additional complexity and several significant limitations.


One of the most important concerns involves write amplification. Because each file corresponds directly to a single object, modifying even a tiny portion of a large file requires substantial data movement. For example, appending only a few bytes to a two-gigabyte video file requires retrieving the complete object, merging the new data, and rewriting the entire object through Amazon's multi-stage append workflow. This process increases latency while consuming additional network bandwidth and storage operations.

Metadata operations also become increasingly expensive at scale. Zhou illustrated this using a simple rename command. Renaming a directory containing one million files in a conventional POSIX file system typically requires only metadata updates. Under S3 Files, however, such an operation eventually triggers background rewrites of every corresponding object because each object's key incorporates the file path. Consequently, operations that appear trivial to applications may generate substantial backend activity, increasing operational costs and execution time.

Additional trade-offs include batching delays introduced by asynchronous synchronization between EFS and S3, conflict resolution policies that always treat S3 as the authoritative source, and an architecture limited exclusively to Amazon Web Services. Customers cannot extend the solution across multiple public clouds or integrate alternative object storage platforms. Pricing also becomes more complicated because organizations pay separately for EFS capacity, EFS read and write operations, synchronization processes, and underlying S3 storage and requests. According to Zhou's comparison, S3 Files successfully delivers POSIX compatibility and directory hierarchies but continues to struggle with in-place updates, efficient metadata operations, application execution, and workloads involving structured datasets.

JuiceFS approaches these challenges through a fundamentally different architecture centered on strict separation of data and metadata. Rather than mapping one file to one object, JuiceFS divides every file into immutable four-megabyte chunks. Metadata—including directory structure, permissions, and file mappings—is maintained independently within a dedicated metadata engine. Because only modified chunks require rewriting, appending data to a large file typically updates only the final chunk rather than recreating the entire object. Similarly, renaming a directory becomes a lightweight metadata transaction instead of triggering extensive object rewrites.

The Community Edition of JuiceFS is released under the Apache 2.0 open-source license and supports multiple external metadata databases, including Redis, TiKV, MySQL, PostgreSQL, and FoundationDB. Users can combine these metadata engines with virtually any mainstream object storage platform, including Amazon S3, Google Cloud Storage, Microsoft Azure Blob Storage, Alibaba Cloud OSS, Tencent Cloud COS, Ceph, and MinIO. Applications access the storage through several interfaces, including POSIX via FUSE, Java and Python software development kits, a Kubernetes CSI driver for container environments, and an S3 Gateway providing compatibility with existing object-based applications.

Recent Community Edition enhancements include configurable storage-class tiering. Administrators can now automatically place directories or individual files into different cloud storage classes such as Amazon S3 Standard-Infrequent Access, Intelligent-Tiering, or Glacier Instant Retrieval. This feature allows organizations to optimize storage costs according to workload requirements without altering application behavior.

The Enterprise Edition expands considerably on the open-source platform. Instead of relying on external databases, it introduces a proprietary distributed metadata engine based on the Raft consensus protocol. This metadata layer scales horizontally while maintaining three-copy redundancy for fault tolerance. Enterprise deployments also gain access to a distributed cache architecture shared across thousands of clients, enabling improved performance for large distributed AI clusters and analytics environments.


Additional Enterprise Edition capabilities include native cross-region replication and multi-cloud mirroring. Organizations may choose cache-only mirrors, where data remains stored centrally while caches are positioned closer to compute resources, or full mirrors that replicate complete datasets across multiple cloud regions or providers. These capabilities support hybrid cloud architectures while reducing latency for globally distributed workloads.

Scalability represents another major Enterprise Edition enhancement. JuiceFS recently increased the supported limit from one hundred billion to five hundred billion files within a single volume. Zhou noted that one existing customer deployment already stores approximately 1.47 pebibytes of data and more than 404 billion inodes, demonstrating that the architecture has moved beyond theoretical scalability into real-world production environments.

Several customer examples illustrated how these capabilities are being used in practice. MiniMax, one of China's leading artificial intelligence laboratories, operates JuiceFS in a hybrid cloud architecture where GPU clusters remain inside the company's own data center while object storage resides elsewhere. Cache-only mirrors position frequently accessed data closer to the GPUs to minimize latency, and the organization is evaluating full replication across multiple locations. JuiceFS argues that this architecture provides the flexibility to balance infrastructure costs against AI training performance without requiring duplicate storage management.

Beyond MiniMax, Zhou highlighted a growing list of customers spanning AI, cloud infrastructure, robotics, internet services, and software development. Named adopters include HeyGen, GMI, PixVerse, Momenta, Horizon Robotics, Xiaomi, Lovart, NAVER, Trip.com, fal, D-Robotics, Cerebrium, Fly.io, and Jerry. These deployments demonstrate the platform's applicability across generative AI, autonomous driving, cloud-native applications, and enterprise software development.

Finally, Zhou discussed JuiceFS's commercial model. Enterprise Edition pricing is based solely on the amount of source-region storage capacity managed by the platform rather than the number of connected clients or compute nodes. This allows organizations to expand large GPU clusters without incurring additional JuiceFS licensing costs. Equally important, JuiceFS does not impose its own data transfer charges because clients communicate directly with the underlying object storage rather than routing traffic through JuiceFS-managed infrastructure. Customers therefore pay only the standard data transfer fees charged by their chosen cloud provider.

Overall, the presentation positioned JuiceFS as part of a broader shift in enterprise storage architecture. Rather than replacing object storage, the company argues that the future lies in enhancing it with higher-level interfaces that preserve cloud economics while eliminating operational limitations. By separating metadata from data, chunking files into immutable blocks, and supporting multiple clouds and storage providers, JuiceFS aims to provide the performance and flexibility of a distributed POSIX file system while retaining the scalability, durability, and low cost that have made object storage the foundation of modern AI, analytics, and cloud-native infrastructure.

Share:

Thursday, June 18, 2026

IO River behind the Soccer World Cup broadcast with a modern CDN approach

IO River used its presentation at the 68th IT Press Tour to introduce a new approach to edge infrastructure management that challenges the traditional content delivery network (CDN) model. Founded in 2022 by CEO Edward Tsinovoi and CTO Michael Hakimi, both former Akamai engineering leaders responsible for edge computing initiatives, the company argues that the architecture underpinning today's Internet delivery infrastructure has failed to keep pace with the growing complexity of cloud-native applications and the explosive rise of generative AI. Rather than building yet another CDN, IO River has developed what it describes as a "Virtual Edge" platform that virtualizes multiple CDN and edge providers into a unified operational layer. Its goal is to provide enterprises with the resilience, flexibility, and performance optimization previously achievable only by the world's largest Internet companies.

The founders' background plays a central role in the company's strategy. During their time at Akamai, Tsinovoi and Hakimi helped develop large-scale edge computing technologies and gained firsthand experience operating one of the Internet's largest distributed infrastructures. According to the company, this experience highlighted an important structural weakness within the industry: despite decades of technological progress, most organizations continue to depend on a single global CDN provider to deliver applications, websites, APIs, and streaming content. While this model worked reasonably well during the early decades of the web, IO River argues that it has become increasingly fragile in an era characterized by massive AI workloads, globally distributed users, and constantly changing traffic patterns.


Since its formation, IO River has attracted financial backing from several prominent investors. The company is supported by S Capital, formerly the Israeli branch of Sequoia Capital, together with Venture Guides, New Era, and Pags Group. In early 2026, it completed a $20 million funding round that increased total investment to approximately $25 million. Beyond financial support, the company has assembled an advisory board consisting of experienced executives from the networking, storage, cloud, and cybersecurity industries. Advisors include Ronni Zehavi, founder of Cotendo and HiBob; Aryeh Mergi, previously associated with XtremIO and M-Systems; Ash Kulkarni, Chief Executive Officer of Elastic and former Akamai executive; Marty Kagan, founder of Cedexis and Hydrolix; Ofir Ehrlich, founder of CloudEndure and Eon; and Pavel Gurvich, formerly of Guardicore. Collectively, these advisors bring experience from companies that have significantly influenced cloud infrastructure and enterprise software.

The central thesis presented by IO River is that today's CDN market remains fundamentally organized around assumptions established during the 1990s. Most organizations select a single CDN provider and entrust that vendor with all edge delivery responsibilities. Although this simplifies procurement and operations, it also creates a single point of failure. The company argues that this model no longer reflects the operational realities of modern digital businesses, particularly those supporting AI-driven applications, globally distributed APIs, or mission-critical online services.

To support this argument, IO River highlighted the frequency of outages affecting major edge providers. According to the company, every major CDN experiences a significant global outage approximately every one to three years, while smaller regional incidents occur on a monthly basis. Even service level agreements promising 99.9 percent availability still permit roughly six to ten hours of downtime annually without financial penalties. IO River cited several high-profile examples from recent years, including multiple Cloudflare incidents lasting between four and twenty-five hours during 2025 and early 2026, AWS CloudFront disruptions lasting seven and fifteen hours, a six-hour Akamai outage in 2025, a seven-hour Google Cloud incident in 2024, and a Microsoft Front Door outage in 2023. Regardless of the precise duration of individual events, the company's broader point was that even the largest cloud infrastructure providers remain vulnerable to significant service interruptions.


From the customer's perspective, the consequences of these outages can be severe. IO River argued that a single twelve-hour outage affecting a major online business could generate customer losses exceeding ten billion dollars through lost transactions, reputational damage, operational disruption, and reduced productivity. In many cases, these financial impacts far exceed the total lifetime revenue earned by the infrastructure vendor itself. As a result, the traditional model of relying on contractual service level agreements offers limited practical protection when outages occur.

Rather than creating another competing CDN network, IO River positions itself as a virtualization layer above existing edge infrastructure. The company emphasizes that it is neither a conventional CDN, nor simply a global load balancer, nor a traditional multi-CDN switching platform. Instead, it describes its architecture as a "Virtual Edge" that separates application services from the underlying infrastructure providers. This abstraction enables organizations to treat multiple CDNs as interchangeable infrastructure resources while managing them through a single operational platform.

The architecture consists of three distinct layers. The first layer focuses on intelligent traffic steering. Rather than directing all requests toward a single CDN provider, IO River dynamically distributes traffic across more than fifteen premium global and regional edge providers, including Akamai, Cloudflare, Fastly, AWS CloudFront, Google Cloud CDN, Azure CDN, and others. Traffic routing decisions are driven by artificial intelligence models that continuously evaluate provider reliability, network performance, latency, and operating costs. Instead of intercepting traffic inline, the platform performs routing through DNS and CNAME manipulation. This architectural choice provides an important resilience benefit: if IO River itself experiences a failure, DNS continues directing traffic according to the most recent routing configuration, allowing applications to remain operational rather than introducing another infrastructure dependency.

The second architectural layer provides unified management and operational abstraction. One of the longstanding challenges of multi-CDN deployments is that every provider exposes different configuration languages, APIs, scripting models, and management tools. For example, Fastly relies on its VCL language while Akamai uses EdgeWorkers and proprietary configuration mechanisms. Maintaining equivalent application behavior across multiple providers therefore requires substantial engineering effort. IO River addresses this complexity by presenting administrators with a single management interface that automatically translates configurations into provider-specific implementations. Organizations can therefore define caching policies, routing behavior, security settings, and operational rules once rather than maintaining separate implementations for every CDN platform.

The third layer virtualizes higher-level application services traditionally bundled within CDN offerings. Rather than relying exclusively on each CDN vendor's proprietary implementations, IO River enables customers to deploy application services independently of the underlying infrastructure provider. These services include web application firewalls, bot management, API protection, edge compute functions, and serverless execution environments. Importantly, IO River does not attempt to develop all these capabilities internally. Instead, it partners with specialized technology vendors, including Check Point, Google, and others, integrating their products into the Virtual Edge platform. The company argues that this partnership model contrasts with incumbent CDN vendors, which historically attempted to develop every capability in-house and consequently often deliver "good enough" implementations rather than best-of-breed functionality.


A major operational advantage claimed by IO River is its ability to detect infrastructure degradation before providers publicly acknowledge service problems. Because the platform continuously monitors performance across multiple CDN vendors simultaneously, it can identify abnormal latency, packet loss, or service degradation in real time. When problems emerge, traffic is automatically redirected toward healthier providers. According to the company, this often occurs before vendors such as Cloudflare or AWS CloudFront officially recognize or announce outages. Consequently, customer applications may continue operating normally while users relying on a single provider experience widespread disruption.

The company also addressed one of the historical barriers to multi-CDN adoption: pricing. Traditionally, distributing traffic across multiple providers reduced purchasing volumes with each vendor, weakening customers' negotiating leverage and increasing per-gigabyte costs. IO River argued that this disadvantage has largely disappeared. Through aggregated purchasing, optimized traffic allocation, and closer collaboration with infrastructure providers, organizations can now maintain favorable commercial terms while simultaneously benefiting from increased redundancy and performance optimization.

Although still a relatively young company, IO River presented encouraging signs of commercial traction. After approximately one year of active sales activity, the platform has acquired around fifty enterprise customers with no reported customer attrition. Initial adoption has been strongest within industries where uptime directly affects revenue, including over-the-top streaming services, online media publishers, gaming companies, and educational technology providers. Representative customers include Minute Media, Nexon, and Plarium. More recently, the platform has expanded into additional sectors including e-commerce, travel, hospitality, and software-as-a-service. One highlighted customer within the hospitality sector is Accor Hotels, illustrating the platform's appeal beyond traditional digital-native businesses.

The company's pricing model reflects its position as an orchestration platform rather than a pure infrastructure provider. Customers pay a tiered platform subscription based on deployment scale, with optional charges if traffic is purchased through IO River rather than directly from CDN providers. Additional usage-based pricing applies to application services such as web application firewall processing or request-based security features. This flexible model allows organizations either to retain existing infrastructure contracts or to consolidate procurement through IO River depending on their operational preferences.

IO River's go-to-market strategy varies geographically. Within the United States, the company primarily sells directly to enterprise customers. In Europe, however, it relies more heavily on systems integrators and regional partners. Examples include GNN in Germany and Equativ in France. Interestingly, the company reported increasing collaboration with CDN providers themselves. Vendors such as Fastly now occasionally introduce IO River into customer opportunities because the platform's visibility into multiple providers helps demonstrate each CDN's unique strengths rather than simply comparing pricing. This evolution suggests that some infrastructure vendors increasingly view multi-provider orchestration as complementary rather than purely competitive.

Operationally, IO River maintains an approximately even split between engineering and commercial functions. Research and development activities are concentrated in Tel Aviv, leveraging Israel's strong cybersecurity and networking engineering ecosystem, while sales, marketing, and customer-facing operations are primarily based in the United States. The company has also filed multiple U.S. patents covering aspects of its Virtual Edge architecture, reflecting efforts to protect its technological innovations as the platform matures.

Financially, the recently completed funding round provides an estimated two-year operating runway, allowing the company to continue expanding both product capabilities and market presence. Looking forward, IO River views generative AI as one of the primary drivers reshaping edge computing requirements. AI applications generate highly dynamic workloads, unpredictable traffic patterns, and increasingly distributed processing demands that challenge traditional single-provider architectures. By abstracting multiple infrastructure providers into a unified operating platform, IO River believes organizations will be better positioned to optimize performance, resilience, cost, and geographic distribution as AI workloads continue to grow.

Overall, IO River presented a vision in which edge infrastructure evolves similarly to cloud computing, where organizations routinely operate across multiple providers instead of depending on a single vendor. Rather than replacing existing CDN providers, the company seeks to orchestrate them, allowing customers to leverage each provider's strengths while minimizing the operational complexity traditionally associated with multi-CDN deployments. Through AI-driven traffic steering, unified configuration management, integrated application services, and resilient architecture that avoids introducing additional single points of failure, IO River aims to make enterprise-grade edge resilience accessible to organizations that previously lacked the resources to engineer sophisticated multi-provider infrastructures. In the company's view, the Virtual Edge becomes the "easy button" for the multi-cloud, multi-edge era, giving businesses of all sizes the operational flexibility, reliability, and vendor independence that until now has largely been reserved for Internet giants such as PayPal and other hyperscale online platforms.

Share:

Tuesday, June 16, 2026

Paradigm4 promotes flexFS, a real alternative to classic high performance file storage

Paradigm4 used its presentation at the 68th IT Press Tour to introduce flexFS, a cloud-native parallel file system designed to bridge the long-standing gap between traditional POSIX file systems and modern object storage. The presentation featured CTO and flexFS inventor Gary Planthaber alongside business development executive Dave Clock, Chief Revenue Officer Andy Cosgrove, and technical sales partner David Freund. Although Paradigm4 is best known for its origins in life sciences analytics, the company argued that flexFS has evolved into a broadly applicable storage platform capable of addressing performance and cost challenges across AI, analytics, machine learning, and enterprise computing.

The story behind flexFS begins with Paradigm4's own infrastructure requirements. While developing large-scale genomic analytics applications, the company needed a high-performance POSIX-compatible file system capable of delivering tens or even hundreds of gigabytes per second in public cloud environments. Existing solutions failed to meet both performance and cost objectives. Paradigm4 evaluated numerous open-source and commercial offerings, including JuiceFS, ObjectiveFS, S3FS, Goofys, S3 Backer, Amazon EFS, Amazon FSx for Lustre, Lustre, DDN, and Weka. According to the company, open-source products generally lacked either full POSIX compliance or sufficient throughput, while enterprise parallel file systems provided the required performance but at price points unsuitable for genomics research organizations operating under constrained budgets.

Unable to identify an acceptable alternative, Paradigm4 developed flexFS internally. Initially built exclusively to support the company's own analytics platform, the file system gradually matured into a standalone product after it became clear that many industries faced the same challenge. Today flexFS has reached version 1.9 and is offered in both commercial and Community Edition forms. The free Community Edition supports up to 5 TB of storage using the customer's own object storage bucket, lowering the barrier to adoption while allowing developers and organizations to evaluate the technology before committing to larger deployments.


Paradigm4 argues that modern AI infrastructure suffers from a fundamental architectural mismatch. Most enterprise applications, AI frameworks, and analytics tools continue to rely on POSIX file semantics, while cloud providers increasingly encourage customers to use inexpensive object storage services such as Amazon S3, Microsoft Azure Blob Storage, Google Cloud Storage, and Oracle Cloud Infrastructure Object Storage. Although object storage provides excellent scalability, durability, and economics, it lacks the low-latency file semantics expected by most software. Organizations therefore compensate by deploying expensive network-attached file systems or maintaining duplicated datasets across multiple storage tiers. According to Paradigm4, these compromises increase infrastructure costs, slow data pipelines, reduce GPU utilization, and ultimately limit AI productivity.

Rather than adapting traditional on-premises parallel file systems for cloud deployment, Paradigm4 describes flexFS as an "object-native parallel filesystem." This distinction reflects a fundamentally different architectural approach. Instead of storing complete files on block devices, flexFS divides every file into multiple chunks. Each chunk is assigned its own object identifier and written directly into the underlying cloud object store. By leveraging the hyperscaler's object infrastructure, flexFS automatically benefits from massive parallelism, scalability, and durability without requiring specialized storage hardware.


One of the major challenges with object storage is metadata latency. Listing directories, locating files, or retrieving metadata can become significantly slower than with conventional file systems. To address this limitation, flexFS employs its own persistent low-latency metadata server. This component maintains the namespace, file attributes, and object mappings independently of the cloud provider, allowing applications to experience near-traditional file system responsiveness while still storing all data inside object storage.

The platform also offers an optional Proxy Group that functions as a write-back cache similar to a content delivery network (CDN). Unlike traditional caching approaches that require entire files to be cached, flexFS supports fractional caching. For example, administrators can configure the system to cache only the first hundred blocks of every file while allowing larger data ranges to stream directly from object storage. This capability enables organizations to optimize cache utilization for workloads that primarily access file headers or metadata while avoiding unnecessary consumption of expensive local SSD capacity.

Paradigm4 emphasized deployment flexibility as another key advantage. flexFS supports single-region public cloud deployments, multi-region architectures, multi-cloud configurations, hybrid cloud environments, fully on-premises installations, and converged deployments where storage services run directly on compute nodes. During the presentation, the company highlighted joint work with Oracle demonstrating performance on Oracle Cloud Infrastructure approaching that of locally attached NVMe storage. This suggests that object-backed storage need not impose the performance penalties traditionally associated with cloud storage.

Beyond core storage functionality, flexFS incorporates several operational features intended to simplify enterprise administration. Duplicate files are identified using hard links supported by checksum verification and byte-for-byte validation to ensure data integrity. The system includes an optimized file search utility driven directly by the metadata server, allowing administrators to perform large-scale directory searches more efficiently than standard POSIX file system operations. Software updates are designed to be non-disruptive, with metadata server pauses lasting less than one second while client mounts automatically reconnect through FUSE session handoff. For containerized environments, flexFS provides a Kubernetes Container Storage Interface (CSI) driver together with Helm charts to simplify deployment into Kubernetes clusters.

Security and resilience are also important components of the platform. Paradigm4 stated that flexFS has achieved ISO 27001 certification, demonstrating adherence to internationally recognized information security management standards. Data durability is rated at eleven nines (99.999999999%), leveraging the inherent resilience of hyperscale cloud object storage. Because flexFS presents a standard POSIX interface, the company positions it as a drop-in replacement for managed cloud file services including Amazon EFS, Amazon FSx for Lustre, Oracle Cloud Infrastructure File Storage, Google Cloud Filestore, and Microsoft Azure Files, allowing customers to migrate workloads without application modifications.

The company illustrated the platform's economic benefits through a detailed customer case study involving one of the world's five largest pharmaceutical companies. Covering a period from September 2022 through March 2026, the deployment grew to approximately 1.14 petabytes containing more than 160 million files. During those 43 months, actual infrastructure costs using flexFS combined with Amazon S3 totaled approximately $2.53 million.

Paradigm4 compared this real-world expenditure against a modeled alternative architecture based on conventional AWS managed storage services. The comparison assumed that storage requirements would be distributed across 25 percent Amazon FSx for Lustre Persistent SSD, 40 percent Amazon EFS Standard Regional, 10 percent Amazon EBS gp3 block storage, and 25 percent Amazon S3 Standard object storage. Under this scenario, total infrastructure spending would have reached approximately $5.65 million over the same period.

The resulting savings exceeded $3.13 million, representing a 55 percent reduction in storage costs. During calendar year 2025 alone, savings reached approximately $1.44 million, or 59 percent. By March 2026, the monthly operating cost using flexFS had fallen to roughly $110,000 compared with an estimated $274,000 for the conventional AWS architecture. The analysis also identified approximately $332,000 in wasted spending associated with over-provisioned Lustre capacity that flexFS eliminated.

Cost efficiency continued improving as deployment scale increased. In 2022, when the environment stored approximately 25 terabytes, effective costs averaged around $90 per terabyte per month. By early 2026, after scaling to 1.14 petabytes, costs had declined to roughly $66 per terabyte per month. Competing managed services remained largely flat throughout the same period, with Amazon EFS estimated at approximately $307 per terabyte per month and Amazon FSx for Lustre around $174 per terabyte per month. Paradigm4 used these figures to argue that object-native storage architectures become increasingly advantageous as data volumes grow.

While genomics remains an important market, Paradigm4 presented several new use cases demonstrating flexFS's applicability across modern AI and analytics workloads. One emerging application is data lakehouse acceleration. In benchmark testing using the TPC-H workload at scale factor 100, Apache Spark combined with Gluten completed execution in just 176 seconds using cached flexFS compared with 1,191 seconds when operating directly on Amazon S3. This represented a 6.8-fold performance improvement, illustrating how intelligent caching and optimized metadata management can significantly reduce analytics processing times without abandoning object storage economics.


Another growing application involves modernization of coupled-architecture database systems. Paradigm4 suggested that massively parallel processing (MPP) data warehouses, graph databases, and vector databases can all benefit from flexFS without requiring application code changes. The company estimates that organizations could reduce total cost of ownership by as much as 60 percent through storage consolidation and improved infrastructure utilization.

Artificial intelligence and machine learning represent another strategic growth area. flexFS supports widely used AI frameworks including PyTorch, TensorFlow, and JAX, providing high-performance shared storage for training datasets, model checkpoints, and distributed learning environments. Because many AI training jobs repeatedly access the same datasets, the platform's caching architecture helps improve throughput while minimizing expensive transfers from object storage. Faster checkpoint operations also reduce training interruptions and improve recovery following hardware failures.

Paradigm4 also introduced the concept of agentic AI workspaces as an emerging workload category. Autonomous AI agents frequently create temporary working files, process very large documents, and require rapid point-in-time recovery when errors occur. flexFS provides POSIX-compatible scratch spaces while supporting efficient byte-range access into large PDF files and other datasets. The platform also enables point-in-time recovery, allowing organizations to restore files accidentally deleted or corrupted by autonomous AI agents. As enterprises increasingly deploy agentic AI systems capable of modifying data independently, these recovery capabilities could become increasingly valuable.

Throughout the presentation, Paradigm4 emphasized that flexFS is not simply another cloud file service but rather a foundational storage architecture intended to reshape how organizations build AI infrastructure. The company believes that the separation between inexpensive object storage and traditional file systems creates unnecessary complexity that affects nearly every modern workload. By combining cloud object economics with POSIX compatibility, flexFS aims to eliminate that architectural compromise while improving performance and reducing costs simultaneously.

Finally, Paradigm4 concluded by raising a broader industry question. Just as the concepts of the Data Lakehouse and Coupled-Architecture Database Management Systems have become recognized categories within enterprise analytics architectures, the company believes there may be room for a new category called the "File Lakehouse." This proposed concept would describe storage platforms that combine the scalability and economics of object storage with the performance and application compatibility of high-performance parallel file systems. During the IT Press Tour, Paradigm4 actively sought feedback from industry analysts and journalists on whether this terminology should be formalized as part of future AI, machine learning, and analytics reference architectures. Whether or not the industry ultimately adopts the label, the presentation clearly positioned flexFS as a technology designed to unify cloud object storage and enterprise file systems into a single architecture capable of supporting next-generation AI workloads at significantly lower cost.

Share:

Tuesday, June 02, 2026

68th Edition of The IT Press Tour in Boston, MA

The IT Press Tour, a media event launched in June 2010, announced participating companies for the 68th edition organized in Boston, MA, the week of June 8th, 2026.

During this edition, the press group will meet 6 hot and innovative companies:
  • ExaGrid, a reference in secondary storage dedicated to backup,
  • IO River, an innovator in CDN,
  • Juicedata, an open source distributed file storage,
  • Paradigm4, developer of flexFS, an alternative to classic highly scalable file storage,
  • Vinchin, a fast growing backup software company form china
  • and Wave Domain, a research project on alternative storage technology.

I invite you to follow us on Twitter with #ITPT and @ITPressTour, my twitter handle and @CDP_FST and journalists' respective handle.
Share:

Tuesday, April 21, 2026

PoINT Software and Systems confirms its leadership in data management

Almost 4 years after we met in Paris PoINT Software & Systems we had the privilege to talk again with Thomas Thalmann, CEO, in Sofia, Bulgaria, for the 67th edition of The IT Press Tour.

PoINT is a privately held German software vendor founded in 1994, with roots in storage and archiving dating back to 1985 through work with Philips and Digital Equipment Corporation. Certified as "Software Made in Europe" and recipient of the Storage Newsletter Cloud Storage Award 2026, the company's core mission centers on helping organizations manage data growth efficiently, reduce costs, and build cyber-resilient storage infrastructures.


The company frames its market relevance around five intersecting categories of pressure facing organizations today: explosive growth in unstructured data and migration complexity on the technical side; rising storage and energy prices on the economic side; data sovereignty concerns on the political side; compliance, archiving obligations, and cybercrime risk on the legal side; and CO2 footprints and e-waste on the ecological side. PoINT's response to all five centers on intelligent data tiering, placing the right data in the right place at the right time, with a strong emphasis on tape as a cost-efficient medium that consumes no energy when inactive and provides natural air-gapping against ransomware.

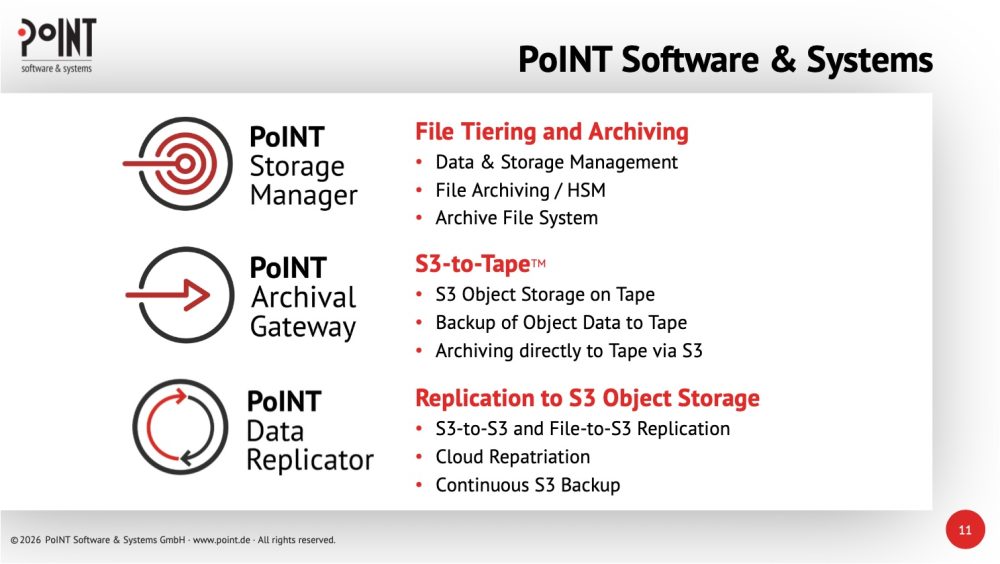
The company offers three main software products. The PoINT Storage Manager, launched in 2007, handles file tiering and archiving by moving inactive files from primary NAS systems to secondary storage including tape, optical, object stores, or public cloud, using policy-based rules while maintaining transparent access for end users. It counts over 200 installations worldwide, with a notable deployment at Daimler spanning multiple locations with WORM, versioning, encryption, and multi-tenancy. The PoINT Archival Gateway delivers S3-to-tape functionality, exposing an Amazon S3-compatible REST API while writing data directly to tape without intermediate disk layers, dramatically reducing costs compared to all-disk or public cloud approaches. Available in Compact and Enterprise editions, the Enterprise configuration scales to 32 interface nodes, 12 tape libraries, 384 drives, and 153.6 GB/s native throughput, with geo-distribution, automatic failover, and erasure coding across two sites. It is also packaged as the ORION S3, a turnkey system developed with BDT offering up to 392PB of native capacity. The PoINT Data Replicator handles backup and replication of object and file data to S3-compatible systems, supporting S3-to-S3 and File-to-S3 modes for use cases including cloud repatriation, legacy NAS migration, and continuous backup via Kafka and SQS change tracking.


Notable customers include Sixt, Daimler, Amgen, PostFinance, and EMBL-EBI, which deployed the gateway to archive Kubernetes workloads via S3 and achieve read/write throughput exceeding 1PB per week. Technology partners include HPE, NetApp, Fujitsu, Dell EMC, Cloudian, and Spectra, with resellers including SVA, Cristie, and Computacenter.


Share: